
How we evaluate design at Gamma
Every month, a new AI model is crowned the world’s best designer. If you believed the benchmark hype, you might think we have reached AGI for design: Models can perfectly design slides, ads, posters, and everything in between in one shot. Yet few of us would let a model build an important presentation unsupervised, much less present its output unchecked.
That’s because real design work is never one shot. It’s a long trajectory of small judgment calls, most with no single right answer, that only make sense together at the end. However, the current benchmarks never evaluate those steps. They look only at the final output, judged in a way that looks nothing like how real design work is reviewed, and collapse everything into a single score.
Don’t get us wrong: models are genuinely impressive. But, their spikes in intelligence are not uniform. They have several gaps, and a single winning score hides both, telling you little about where a model shines or how to put it to work.
At Gamma, we serve more than 100 million people, from educators and architects to brand executives to business analysts. Every request, whether a new deck or a single edit, is handled by our agent, which contracts a pod of models as the task requires. Doing that well means building evals that measure what a single score can’t. Here’s how we think about evals.
Every task arrives with a rough budget in someone’s head:
Speed: how much time they’re willing to spend?
Cost: how much money they’re willing to pay?
Quality: what result they’ll accept for that combination.
This budget is never spelled out aloud. A good designer works it out before starting the job, figuring out what’s non-negotiable and what’s flexible. We hold our agent to the same standard: infer the bar from the task, make the trade-offs the person would make, and get better at both with every request.

Once we know the bar, we measure quality in two ways:
Acceptance: does the output clear the bar as is? Could the person present or share it without edits?
Repair ratio: if it doesn’t, how much work does it take to get there, compared with doing it from scratch?
Acceptance is hard to measure, especially for visual work. Repair ratio is more concrete: how much fixing does it need before you’d use it? Because every deck on Gamma is edited in our editor, we can see what happens after the first draft: how many changes people make, how long they spend, and what they keep fixing. A deck that’s 75% there isn’t a win if it takes three hours to get it on brand, or if one wrong summary sends you back to fact check three documents. If fixing it takes longer than making it yourself, the agent hasn’t saved you anything.
To see where the fixing comes from, we score each step a designer would take. At every step in the design trajectory, we measure a verifiable signal of success, and added up, those signals tell us whether the agent is moving the work closer to what the person wants, within the speed, cost, and quality they’ve set.
Here’s a snapshot of three things that get scored along the way:
Instruction following: Did it do everything you asked, explicitly?
Craft: Does it meet the standards a trained designer would hold to, without being told?
Judgment: Where there’s no single right answer, does it make the call that fits you and the task, including knowing where to find the context it needs?
Instruction following
Did the agent do everything you asked for explicitly?
1. Straightforward asks
Say you ask: “Make a five-slide deck introducing our team, our Q3 wins, and our roadmap. Don’t forget to add the logo to the footer of every slide.” If the logo is missing from slide four, or it ends up in the header instead, that’s a failure.

2. Asks with multiple valid answers
Some instructions are explicit, but there can be multiple right answers at the same time.
Example, “Make this deck fit a 20-minute talk” could mean either of these:
8 slides, visually light. The presenter carries the story through their delivery.
18 slides, information-dense. Works for an in-person presentation and as a shareable deck for attendees to read on their own later.
If the agent makes too many assumptions about the person, there’s a good chance it won’t meet their requirements. In cases like this, the agent will present a few valid options to choose from instead of guessing.

3. Explicit Constraints the Agent must Respect
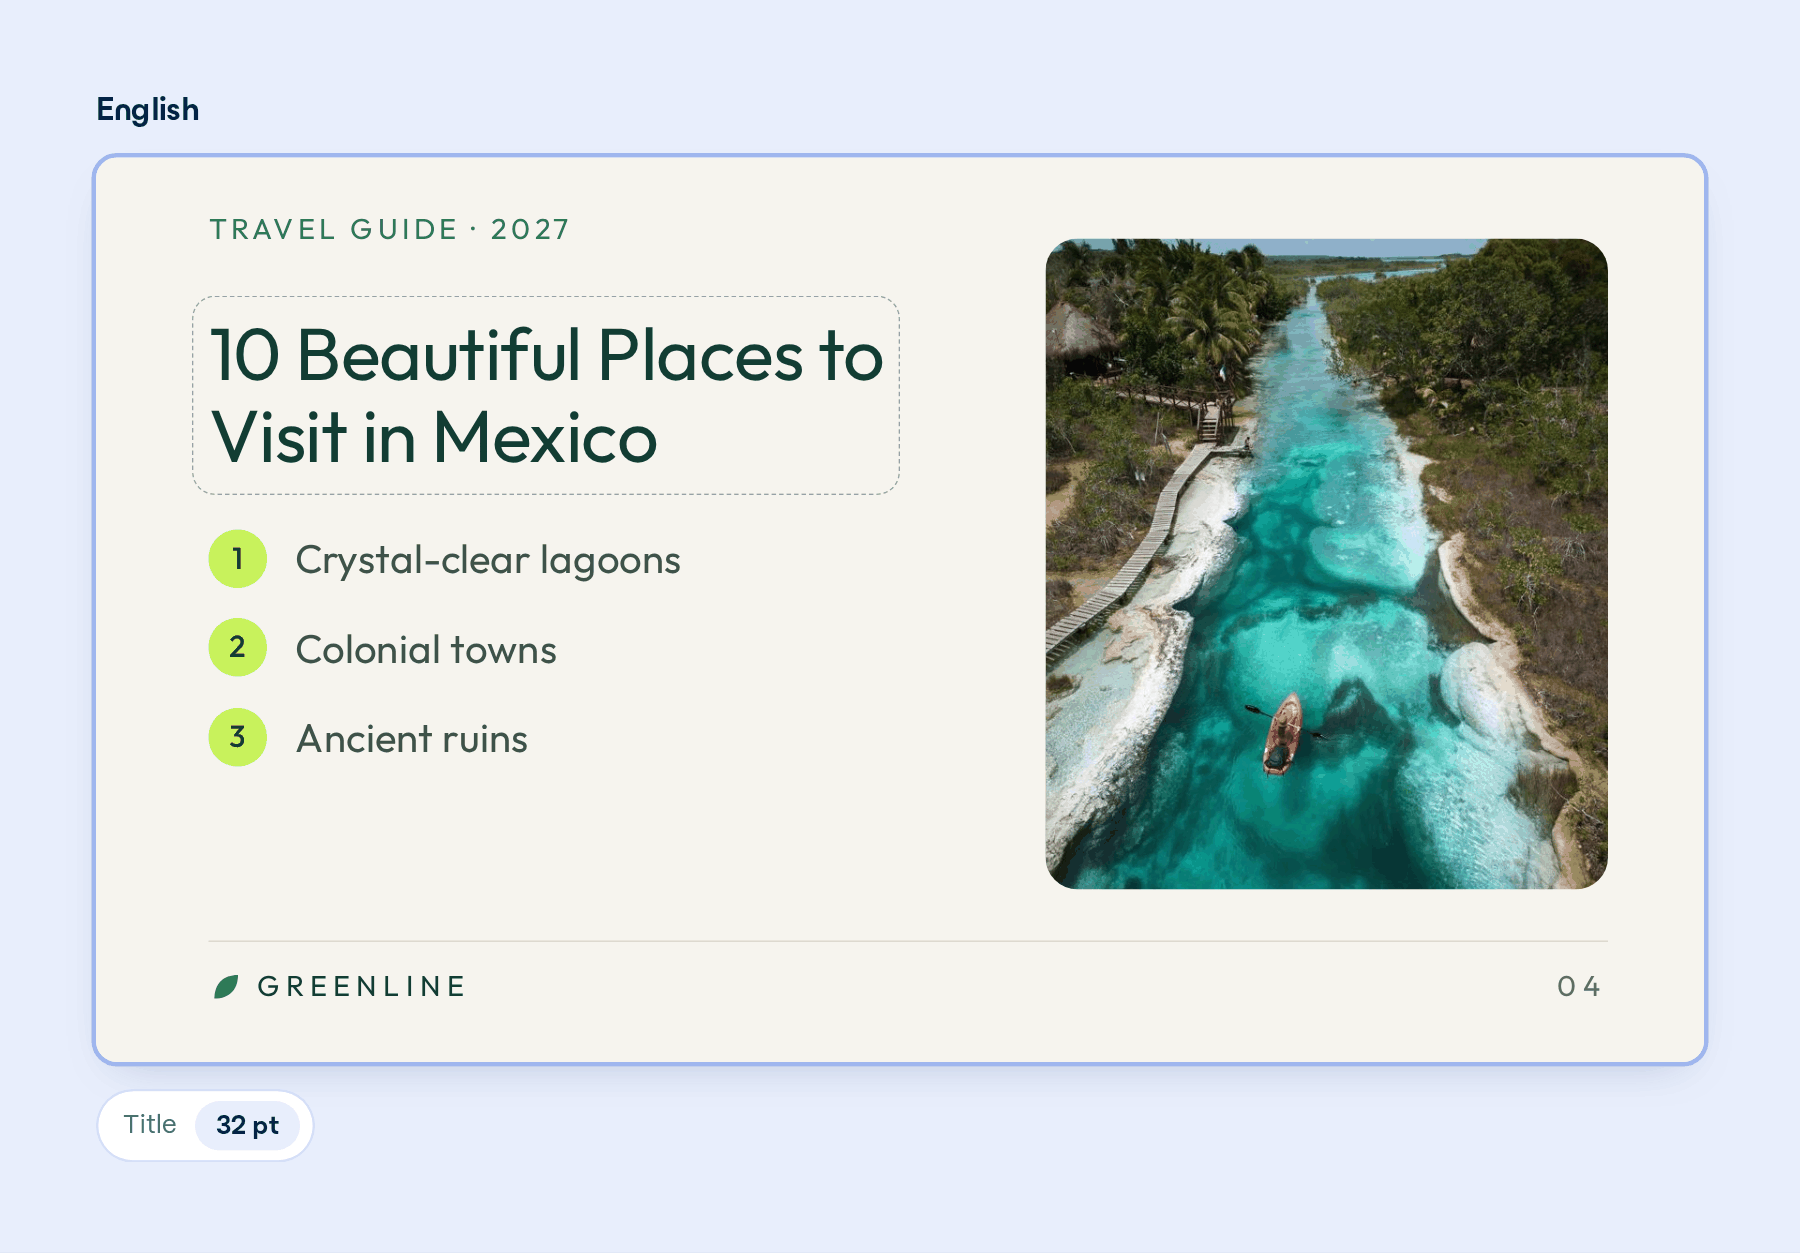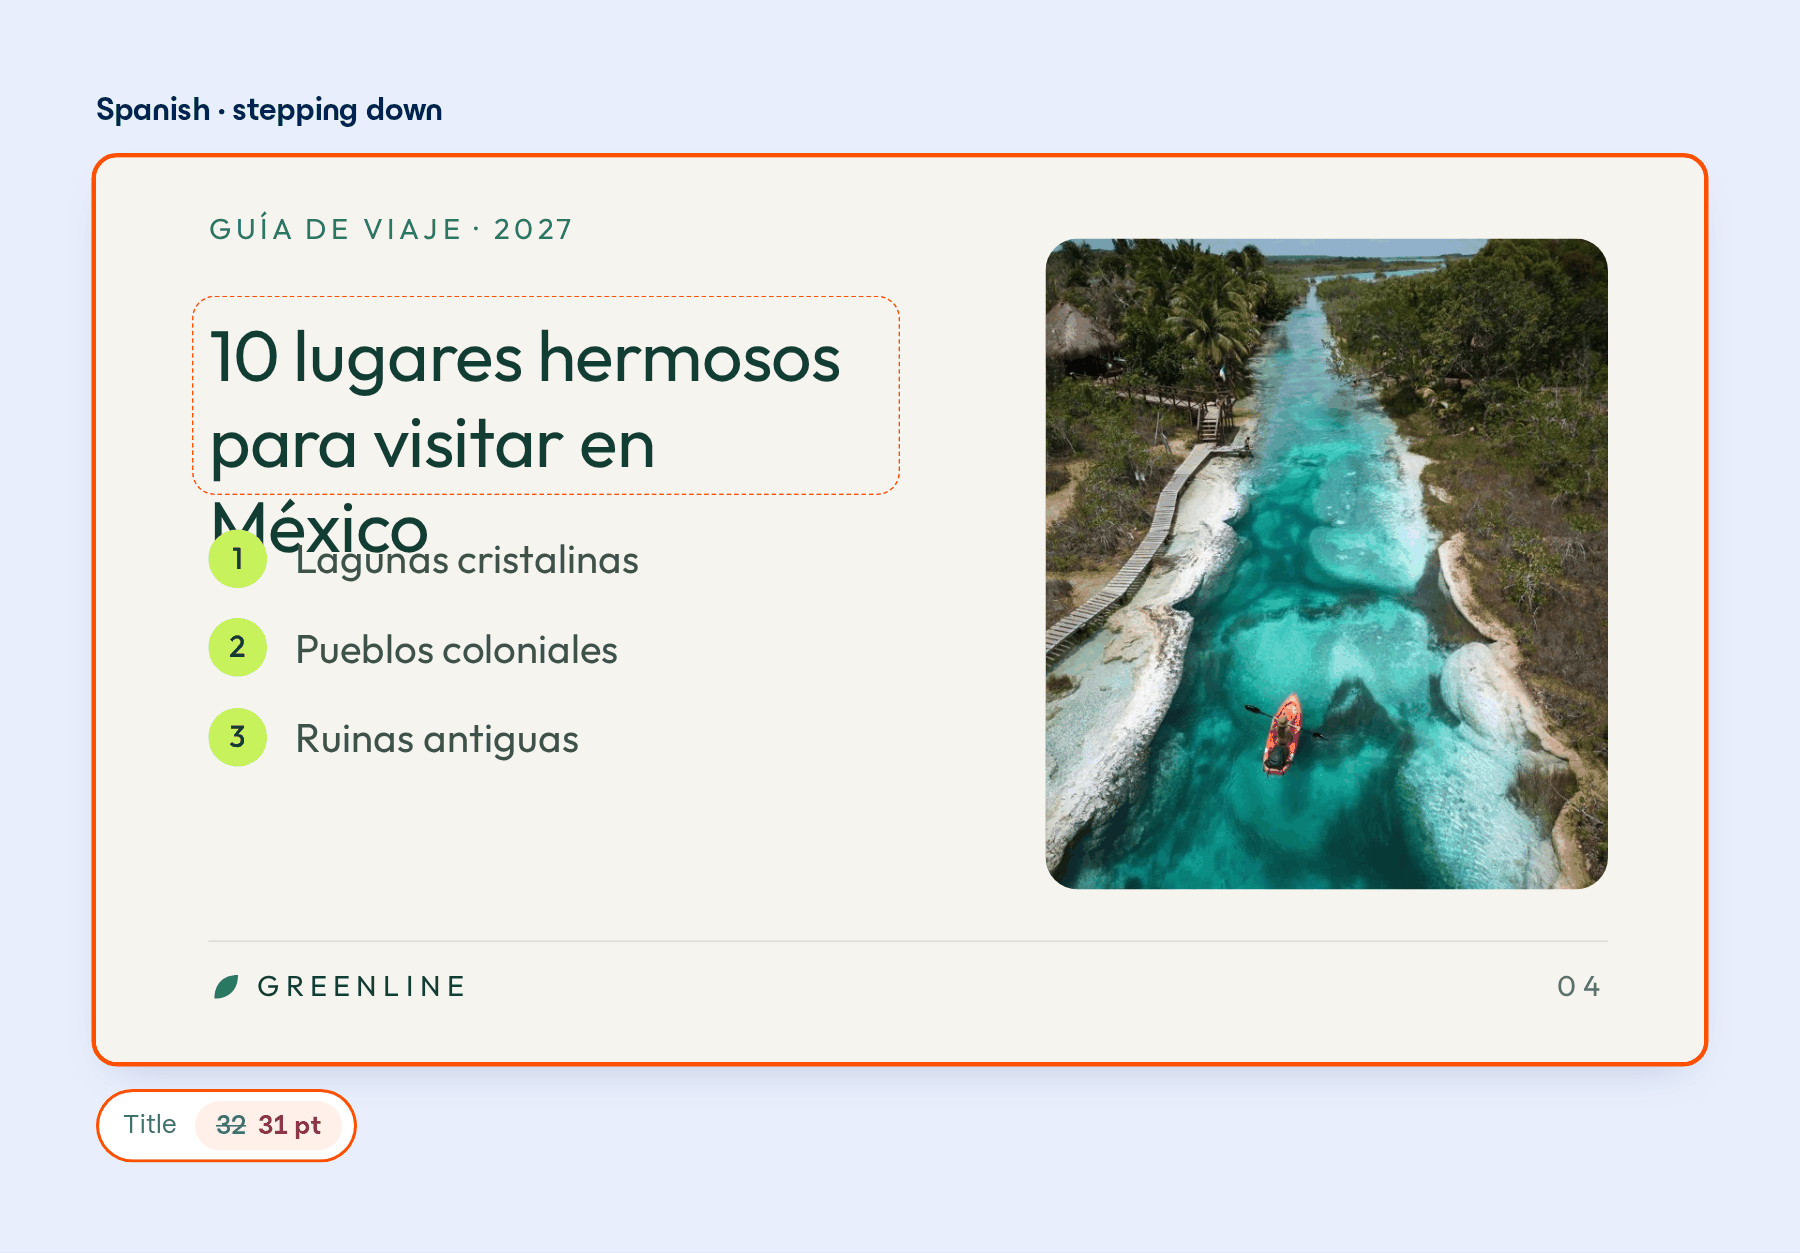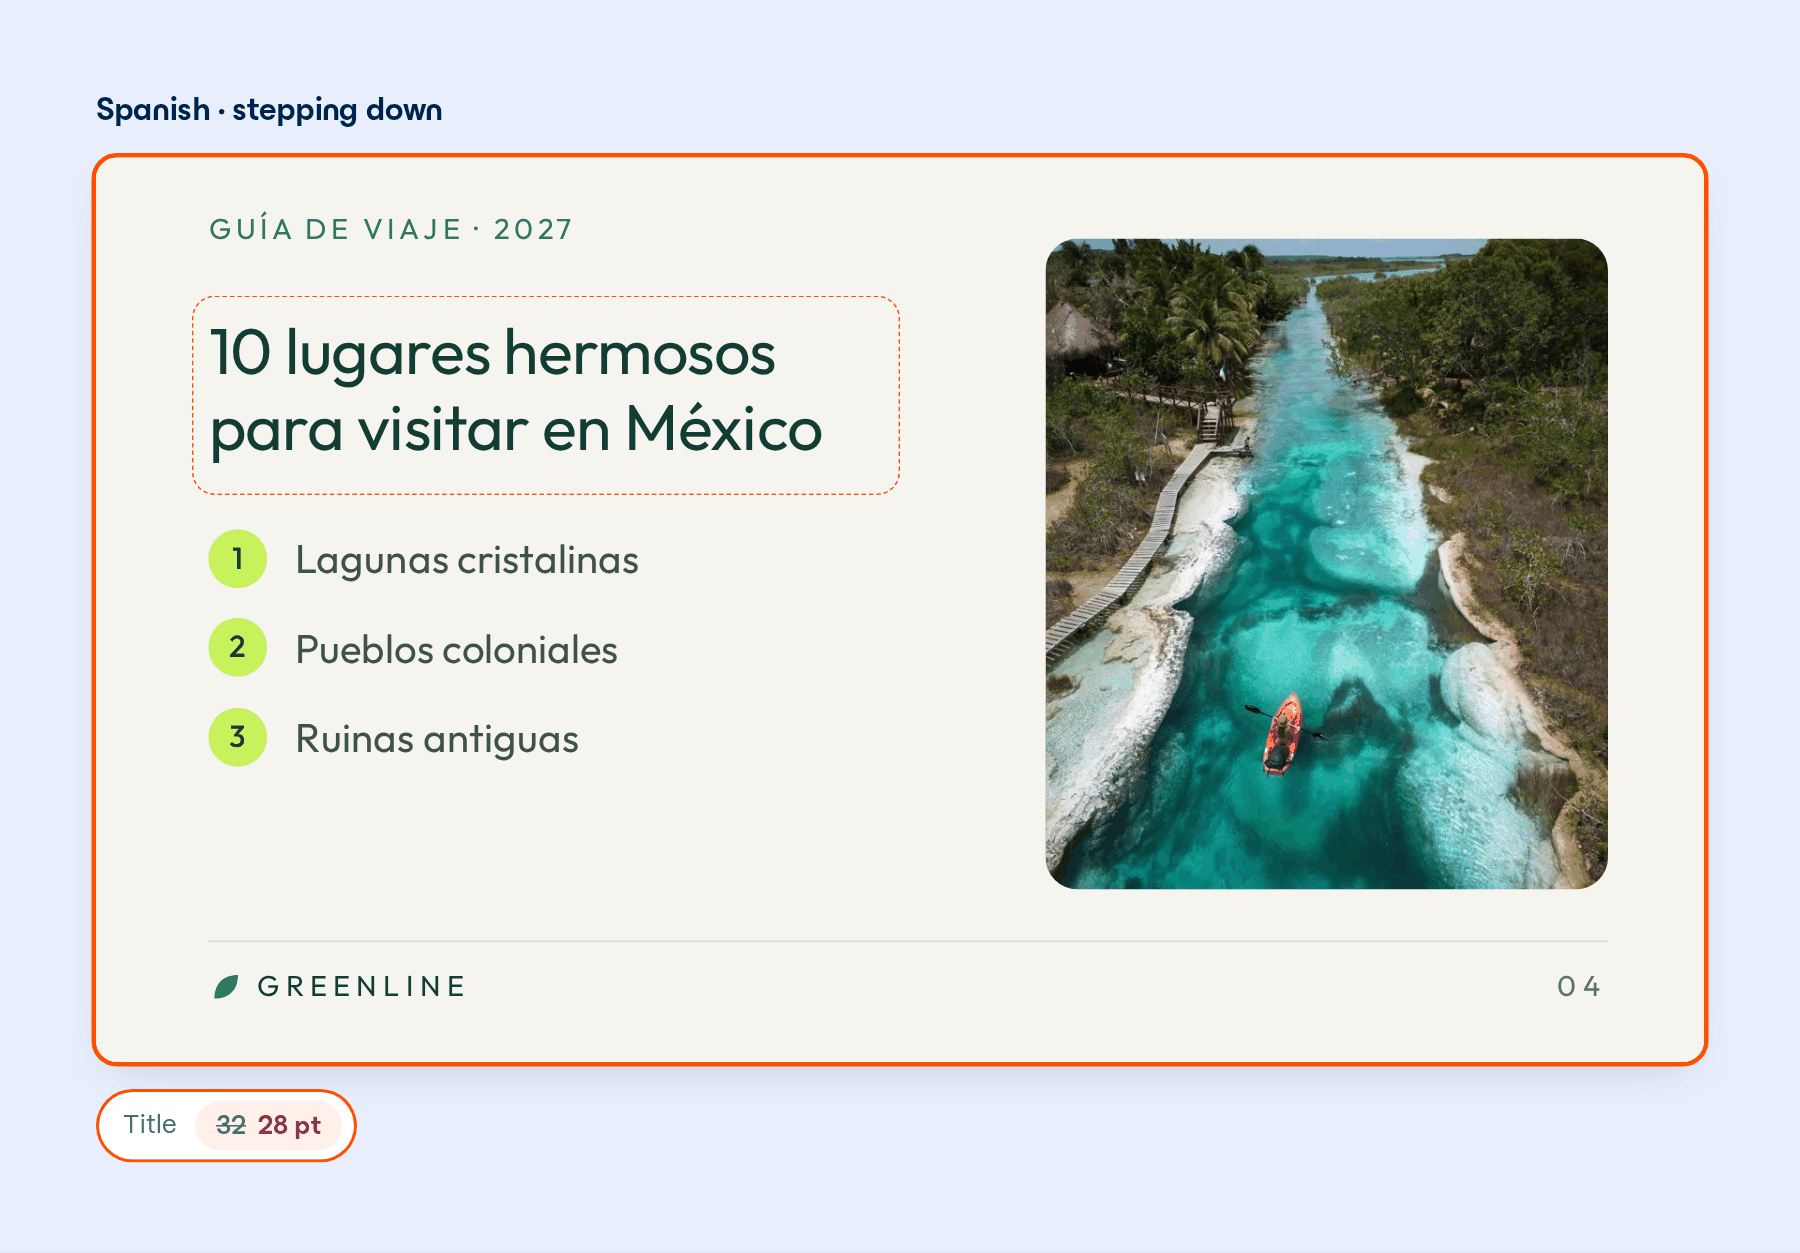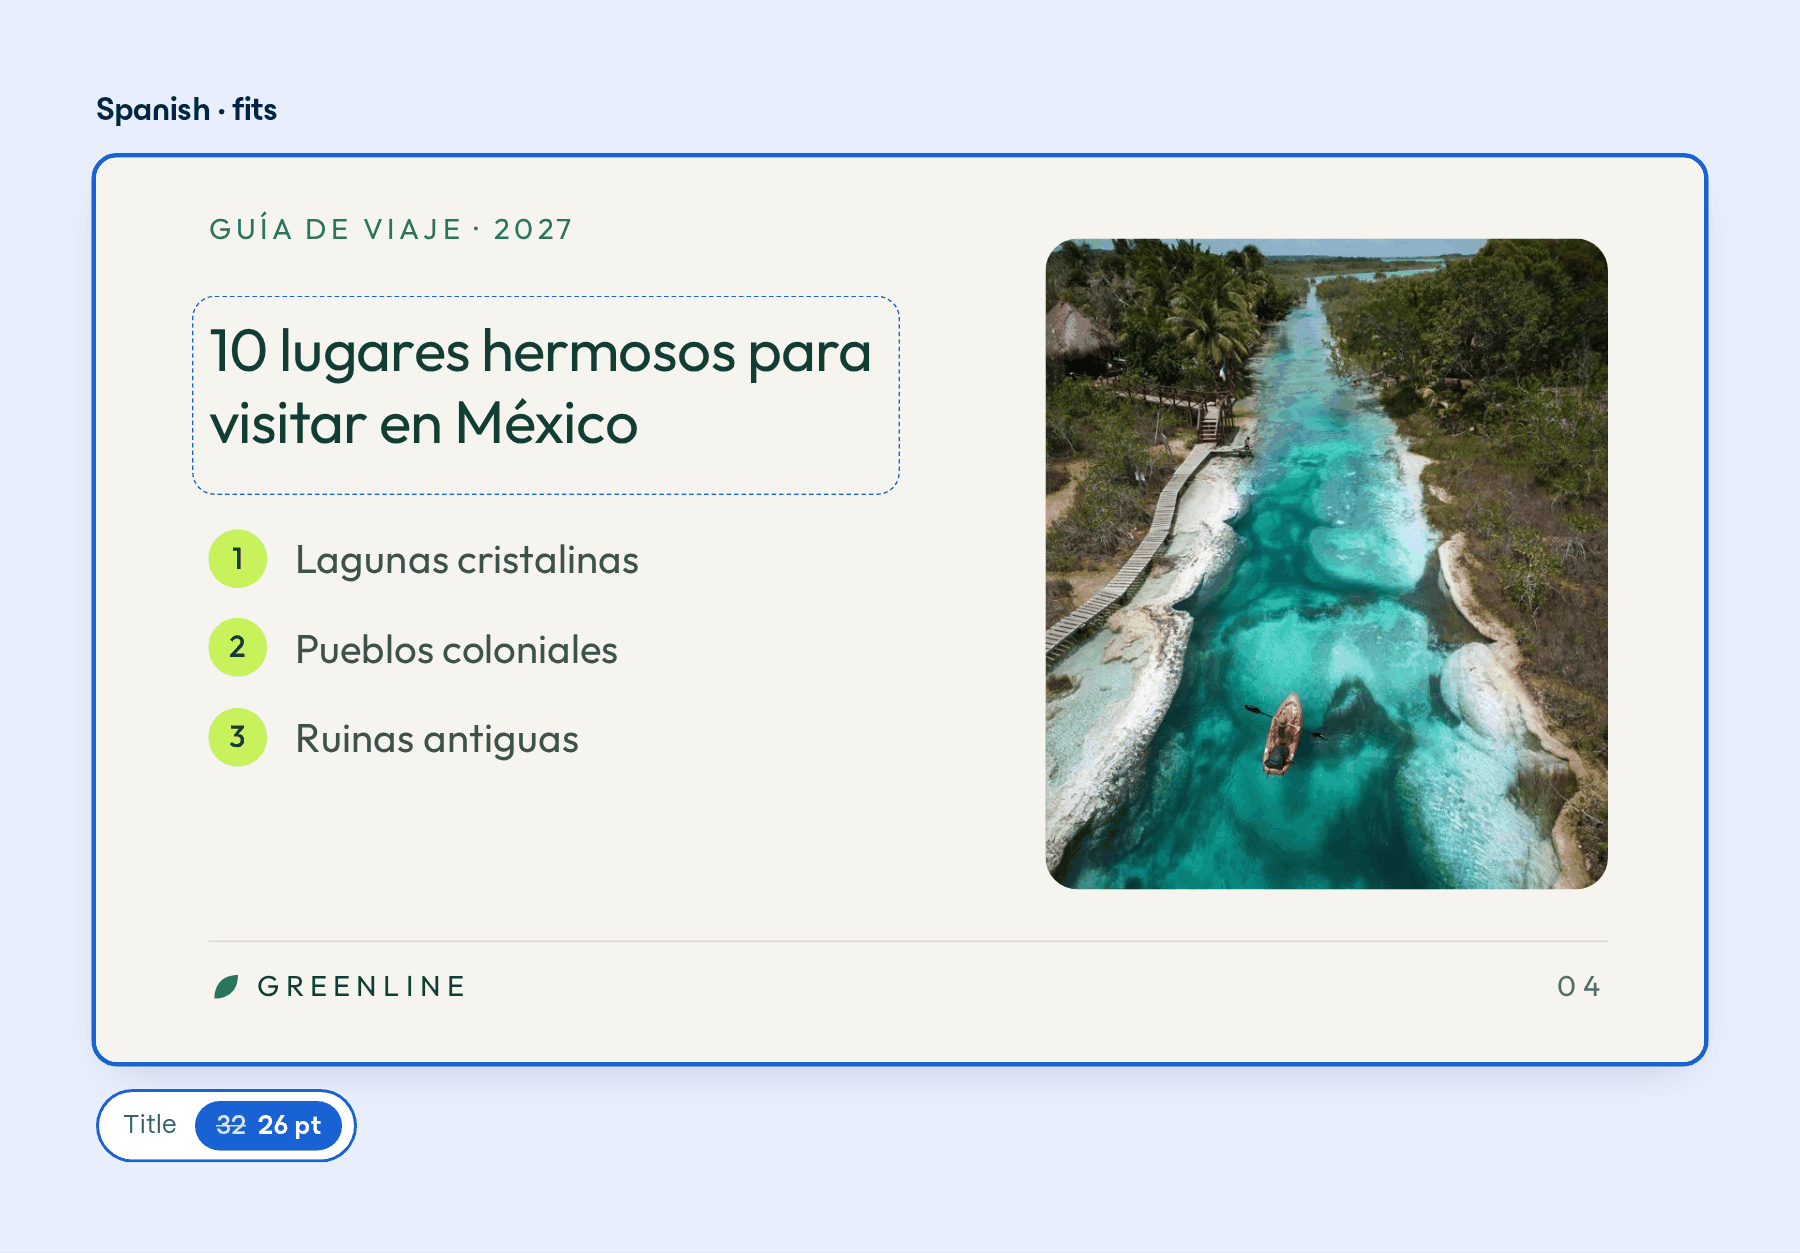
Other instructions are about what to leave alone. Let’s say you want a deck to be translated to Spanish, and you want to preserve the template style used for English. But, Spanish translation can run longer, so if you just swap the words out, the text will overflow in the container. The right call is to keep the box exactly where it is and step the type size down until the text fits.
Craft
Adherence to established design principles, unstated but always expected.
These are the standards you’d expect from any good designer without having to spell them out: text you can read, nothing crashing into images, and fonts and colors that match the brand. You’d never write “make sure the title is readable” in a brief, but you’d notice right away if it wasn’t.
Say the agent is asked to make a title slide for “Sustainable Cities: A Singapore Story.” You supply the image to be added. The photo is stunning and the type is beautiful, but the title lands on the busiest part of the image and disappears. That’s a fail.
There are several good fixes: a gradient rising behind the title, a side-by-side layout with the text on a solid color, a duotone treatment, or the photo framed beside the title. The agent runs through these trajectories, and each one passes the legibility check. The one it picks is the fix that aligns with the brand guidelines and harmonizes with the larger theme of the deck.

Judgment
There is more than one right answer.
Some design tasks have no single right answer, so part of the agent’s job is shortlisting a few valid paths and picking the model best suited to execute them.
For a slide on Singapore’s Gardens by the Bay, accuracy comes first: a real photo from the official site beats a generated one, which could look stunning and still get the photorealism wrong.
A moodboard on “cities in 2050” asks for the opposite. It’s about imagination, not realism, so the agent reaches for an image model with a creative streak, one that sparks new ideas for the person while still getting the details right: buildings that look like they could stand, light that falls the right way. A model built for photorealism, which leans on reference images to compose a scene, might hand back something that looks like a stock photo parody of the future, so it wouldn’t get picked.

Picking the right image model
Say the agent has to add icons for each stage of a drug pipeline in this slide. With the slide’s design already planned, there are two ways to build the icon tray: rich illustrations from an image model, or outline icons written as SVG code. Both could work for some brands, but this one uses minimal outline icons. And, the agent cannot ignore the brand guidelines.
There’s a technical catch too: an image model hands back a PNG file, which won’t survive theme recoloring and loses resolution when scaled. A coding model writes SVG, which stays sharp at any size, follows the deck’s theme, and aligns with the brand guideline.
So the judgment call is contracting the model that can preserve that brand guideline: clean lines, consistent strokes, and nothing extra, without getting sloppy. There are only a few models eligible to execute this task, and the model picks the one that does.

Gathering context
We are not saving you time if we just hand you a deck that looks good visually, but the content takes forever to populate. The agent must know which tools to call to pull the right context to complete the presentation: your meeting notes, your latest numbers from analytics tools, and your workspace’s brand and templates. Gathering it is a judgment call too.
The prompt rarely says where to look, so the agent has to know where each piece lives and go find it, instead of stopping to ask you.
For example, “create a QBR deck for next week’s meeting and highlight the blockers discussed in yesterday’s all-hands Q&A,” the agent goes to Granola, for the meeting notes to identify the blockers discussed, the Power BI dashboard for the latest numbers.

These are just a few of the many nuanced decisions the agent is tasked to make when designing a presentation, no different from what you as a knowledge worker would be expected to make. Many of the calls that seem obvious to us as people, aren’t yet obvious to models. While our evals are by no means perfect, a big part of our mission is to build agentic systems that can exercise the judgement that aligns with your expectations.
Leaderboards will keep crowning a new best designer every month, and honestly, we love the competition. But great taste is the summation of hundreds of details we obsess about. The top ranked model may not always care about those exact details. That nuance is what we set out to measure.
It’s an exciting time to be doing this work: every day, we find new ways to surface the latent strengths of models, put them to work on real decks, measure how they do, and bring the best of them to you, aligned with your personal taste and your brand’s. Evals are an ocean, and in the posts ahead, we’ll dive into each slice of presentation design, one at a time.


